Editors & reviewers
Collect a review handoff
Gather comments, authors and reply references into a readable report before assigning revisions.
Bring comments and highlights into one clear report.
Expand an annotation below to locate it on the page. The blue outline is only a preview aid.
No matching annotations on this page. Try another page or include more annotation types.
Download your report or choose another format below. Your PDF stays unchanged.
No matching annotations were found. The export contains no annotation rows. Use Back to change the filters or choose another document.
Choose a PDF with comments, highlights or other annotations, or try the sample.
Browse pages, expand a comment and choose the annotation types to include.
Download a CSV spreadsheet, readable text report or structured JSON.
Export PDF Annotations collects real PDF comments, text highlights, drawing notes and other annotation details into CSV, plain text or JSON. Browse the document first, then export the current page or all pages without uploading the PDF.
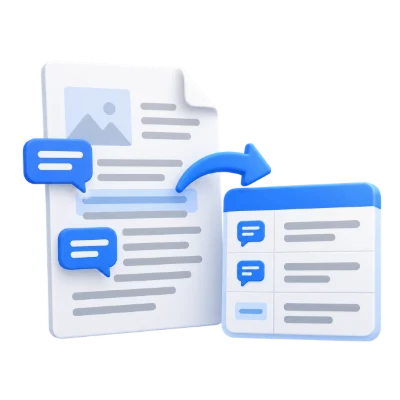
Gather comments, authors and reply references into a readable report before assigning revisions.
Export marked text from selectable PDF pages alongside your notes, with page numbers for reference.
Open the CSV in Excel or another spreadsheet app to sort comments by page, author or annotation type.
Use the page thumbnails and expand an annotation below the preview to see its comment and location.
The preview lists only the current page, with eight entries at a time when there are many annotations. Expanding a row shows the written comment, subject, recoverable marked text and a reply reference when present. The blue location outline is a preview aid.
The count in Settings follows the current page and chosen type filters. It is not a count for the whole document. Scanning all pages starts when you choose Export annotations.
Export all pages by default, or use Current page. Include the groups relevant to your review.
Comments & text notes includes sticky comments, free text and insertion marks. Highlights & text marks includes highlighting, underlining, wavy underlining and strikethrough. Drawings & shapes covers lines, shapes and ink strokes. Stamps & other annotations includes other readable annotation records.
Every included annotation becomes one report row, even if it has no written comment. Replies remain separate rows and can reference their parent ID. Link annotations, popup containers and interactive form fields are excluded. Attachment annotations can contribute their note, but attached files, stamp images and drawing geometry are not exported as reusable assets.
Include marked text is enabled initially. It reads selectable characters covered by text-mark annotations.
The tool uses character positions to recover selected words and multiple marked lines. Existing Arabic comments and recoverable Arabic text are supported. CSV and TXT use UTF-8; JSON keeps Unicode text. Complex writing order or broken character maps in the PDF can still affect the extracted passage, so review important quotations.
Image-only scans have no selectable text to recover unless an OCR text layer was added earlier. Their real comment annotations can still be exported. Turn Include marked text off if you only need comments and metadata or a difficult page exceeds the extraction limits.
Choose the main download format before exporting. All three versions are also available on the result page.
CSV provides page, type, author, subject, comment, marked text, creation/modification dates, annotation ID, reply reference and review state. Spreadsheet-like formulas in text cells are escaped for safer opening; use JSON or TXT when you need those strings without the spreadsheet escape. Import the CSV as UTF-8 if your spreadsheet does not detect it.
TXT is a readable report with localized headings. JSON provides structured records, including original annotation type names, color values and page-relative bounds. Dates are UTC when present. These are reports, not XFDF/FDF backups for restoring annotations to another PDF. Missing authors, dates or comments remain blank.
The PDF is read on your device and a separate report is generated. No annotations are removed or applied.
Open one unencrypted PDF within the displayed file and page limits. The original document is not uploaded. Large files or dense comments may take longer; processing remains bounded and reports an error rather than quietly omitting records when a limit is reached.
If there are no matching annotations, the result explicitly says so and the report contains no annotation rows. Back lets you revise filters or choose another source page. Start over clears the workspace. Download the report before closing the page.
Open one PDF up to 100 MB and 750 pages. Additional output, memory and processing limits can apply to complex documents.
Up to 20,000 annotations can be inspected per export. Very large comment text or exceptionally complex marked-text selections may require a smaller selection.
Processing takes place on your device without uploading the document. Download your result before closing the page; keep the original separately.
Know what to expect before you start.
On your deviceOpen the PDF, choose CSV and export the annotations. Open the CSV in Excel or import it as UTF-8. Each matching annotation has its own row; this tool does not create an XLSX workbook.
Enable Highlights & text marks, turn off the other groups and leave Include marked text enabled. The report includes the text recoverable beneath each text mark and its associated comment. Other text marks such as underlines remain in that group.
All pages is selected by default. Choose Current page to export only the page currently shown. The preview list always describes the current page.
The page may have no matching annotation objects, or the chosen filters may exclude them. Marks flattened into page content are not recoverable annotations. Try another page or the provided annotated sample.
Yes, when stored in the PDF. Replies are separate entries with a reference to their parent annotation, and author, subject and available dates are included.
Arabic comments and Unicode reports are supported. Marked Arabic text can be recovered when the PDF has a usable text layer; unusual encodings or reading order may require checking the passage.
No. CSV, TXT and JSON are review reports, not XFDF or FDF interchange files. They do not recreate stamp images, pen strokes or attached files.
No. The document is read in your browser and the report is generated locally. Download it before closing the tab.