

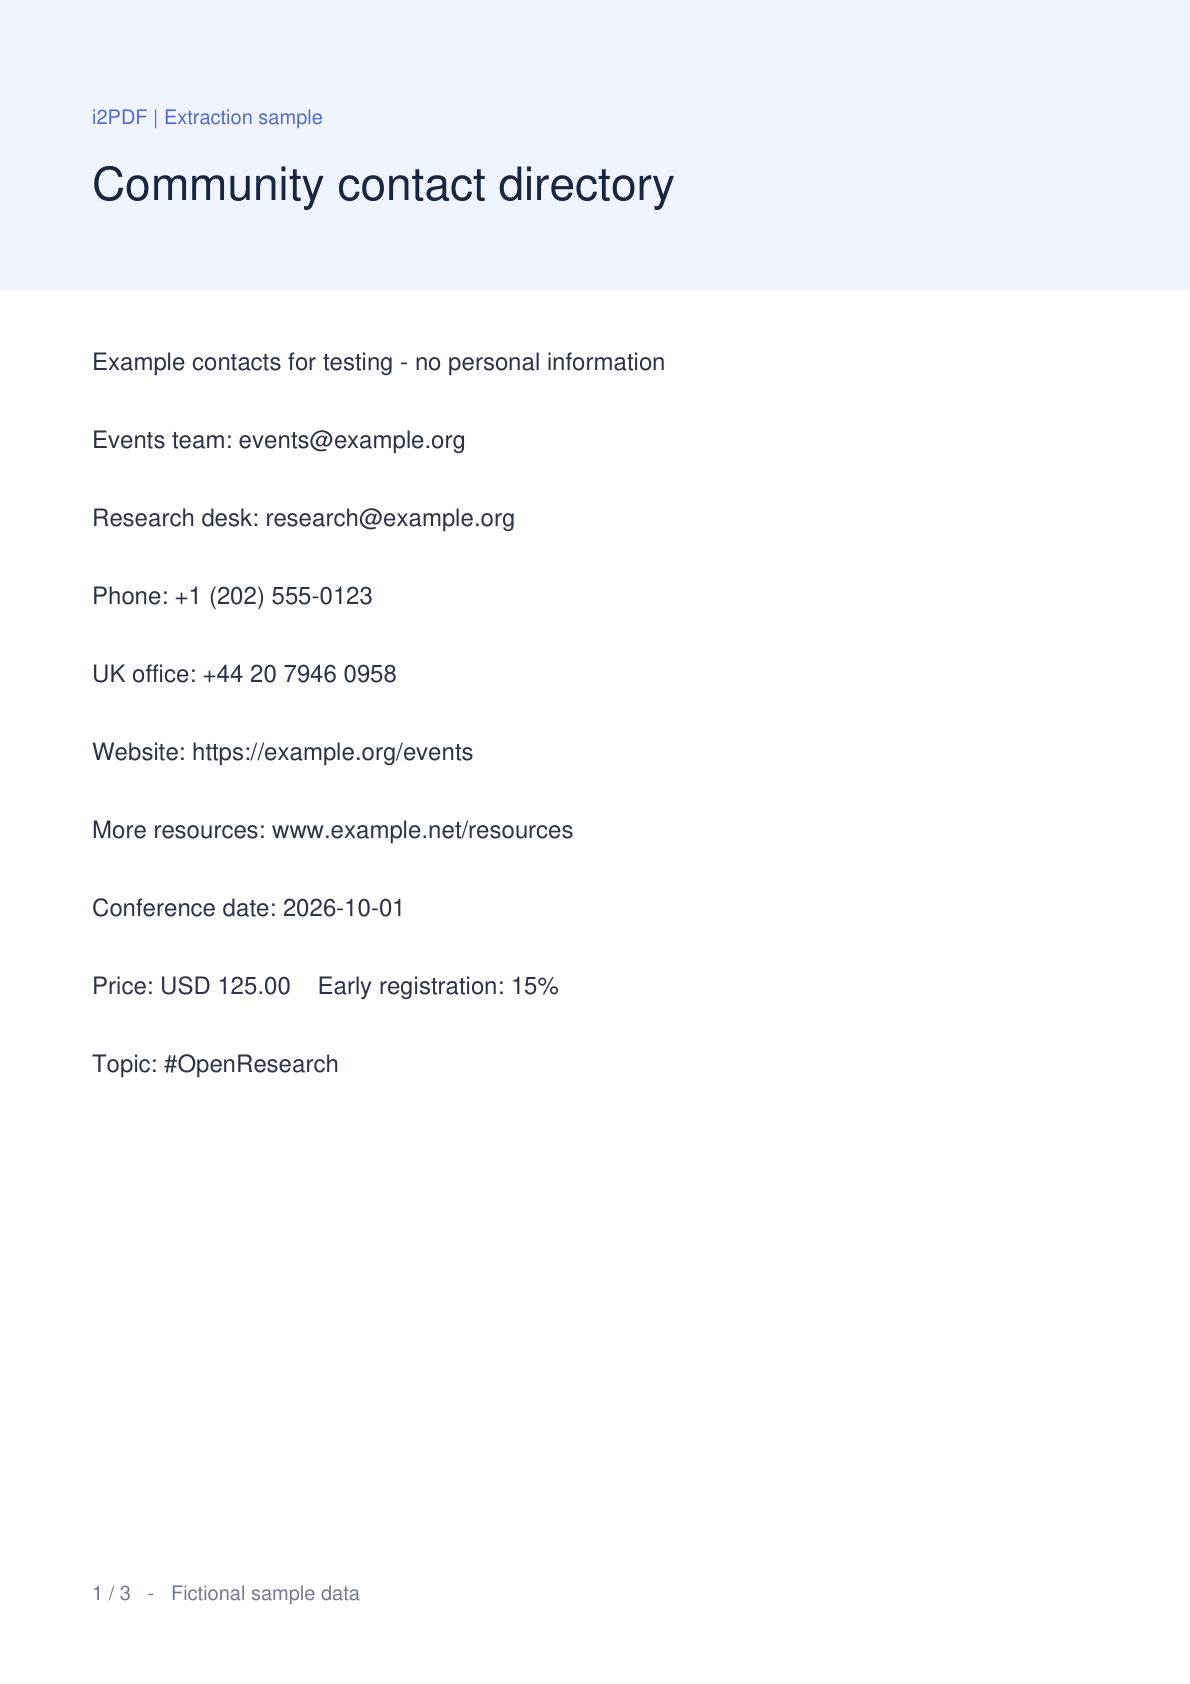
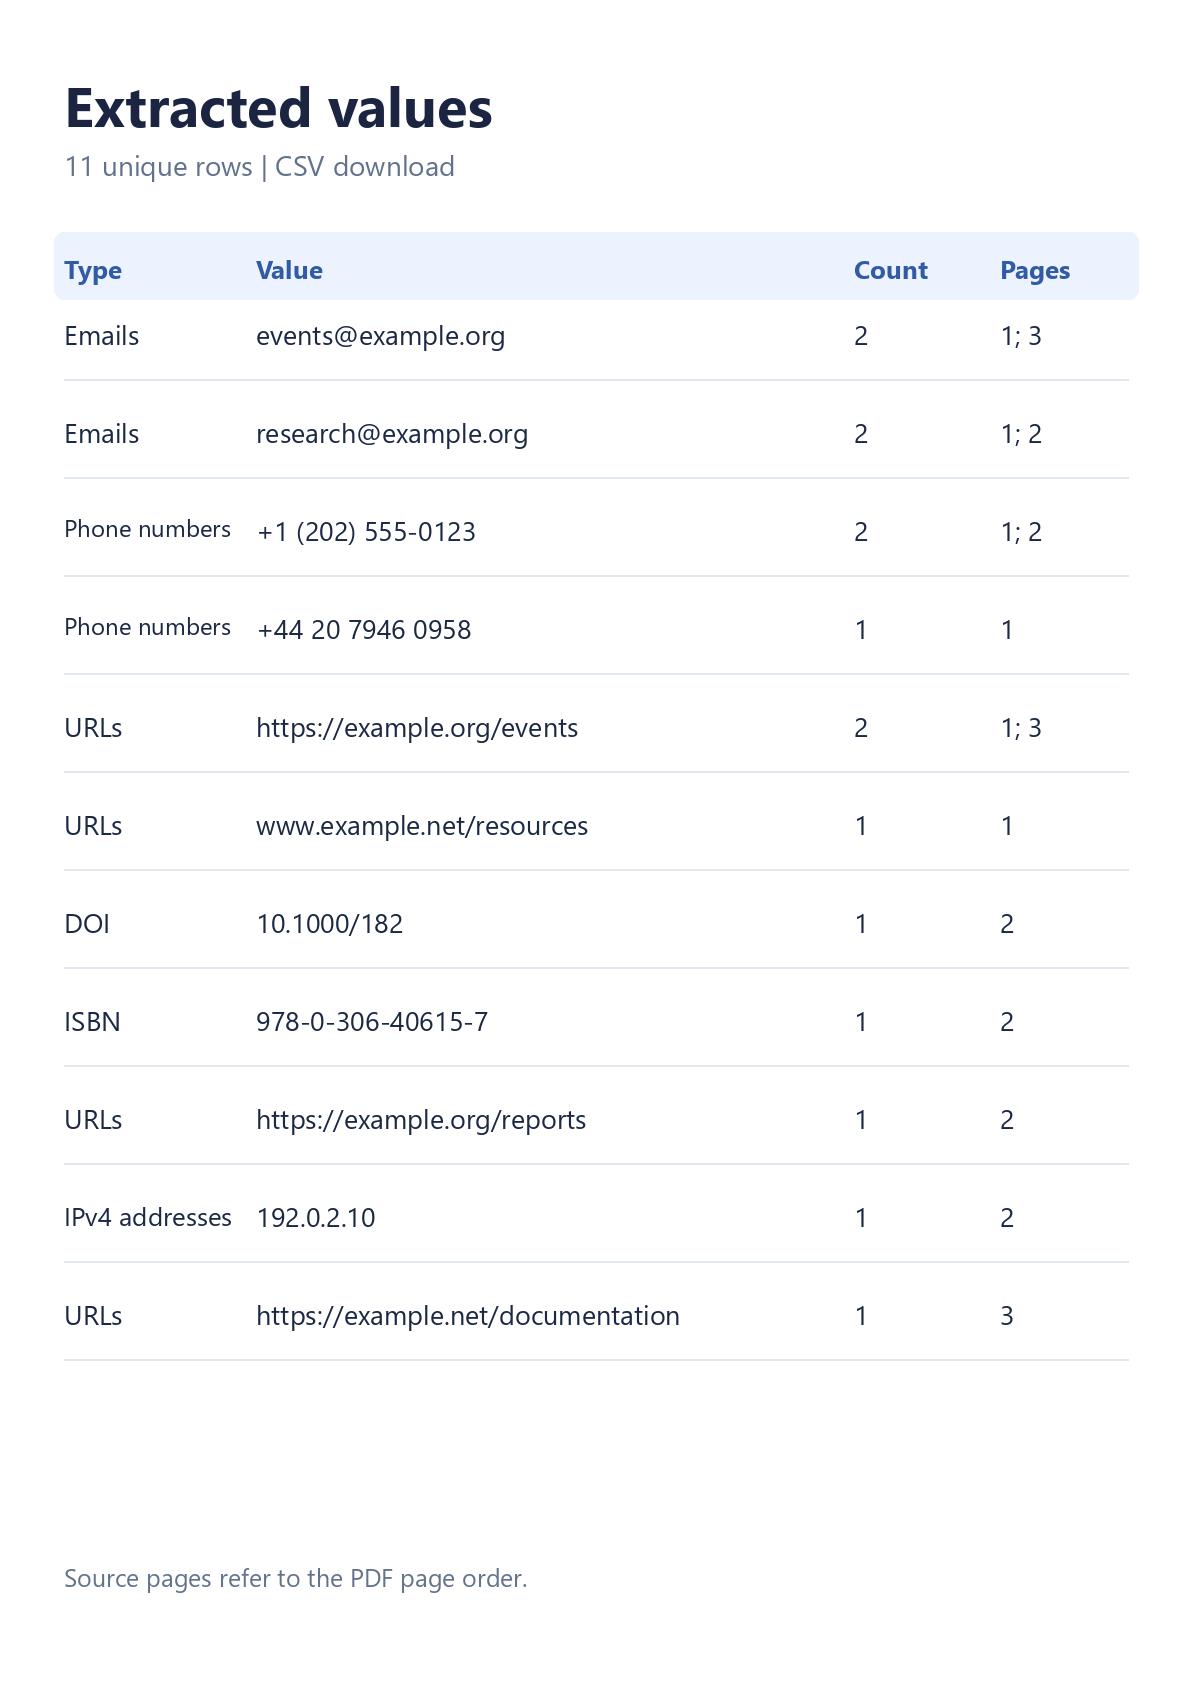

Open Extract Data from PDF to collect values from one PDF without copying them line by line. The comparison uses the real sample document and a CSV downloaded from the tool. With emails, phones, URLs, DOI, ISBN and IPv4 selected, the three-page sample produces 11 unique rows from 15 occurrences.
Open your PDF
Upload one PDF, or select Try sample to follow this example. The PDF preview and page thumbnails appear. Your original file stays unchanged, and extraction runs in your browser.
A text-based directory, report, research paper or brochure is a useful starting point. Image-only scans need OCR before their printed text can be recognized.
Choose the useful options
On a phone, open Settings. On desktop, use the settings panel beside the preview.
Under What to extract, emails, phone numbers and URLs start selected. Open More data types and also select DOI, ISBN and IPv4 addresses. Leave duplicate removal enabled and choose CSV.
Extract and check the matches
Select Extract. When processing finishes, the Results tab shows the values, occurrence counts and source pages. Select a circular page number to inspect its location in the PDF preview, then return to Results.
The output combines the contact list with DOI 10.1000/182, ISBN 978-0-306-40615-7 and IPv4 address 192.0.2.10 from page 2. The Type column identifies each value. Filter to a relevant word or identifier before copying or downloading a smaller subset.
Use Filter results to narrow the list. Copying and downloading include all matching rows, even when the result table spans several screens of rows.
Download CSV or TXT
Select Download CSV, then use the main Download button on the ready screen. CSV contains Type, Value, Count and Pages columns. TXT and Copy all contain one value per line.
CSV values that could be interpreted as spreadsheet formulas are protected with a leading apostrophe. For example, an international phone number begins with a plus sign. Use TXT if you need a plain list without spreadsheet protection.
Common questions
Does this extract any number or every identifier?
No. Each selected category has its own recognition rules. IPv6, percentages, prices and payment-card numbers are not extracted. Review matches against the source; valid formatting cannot confirm that a contact or identifier exists.
What should I do with a scanned PDF?
Run PDF OCR first, then load the recognized copy into this tool. Check OCR output carefully: a mistaken character can change an address or identifier.
What are the extraction limits?
Use one PDF up to 50 MiB and 750 pages. Extraction is bounded to 20,000 matches overall and 2,000 per page, with a 90-second processing budget. Text and annotation limits also apply. If a limit or unreadable page interrupts the scan, the tool shows a partial-results notice and marks the export filename as partial.
Are my PDF links opened automatically?
No. Extraction reads the file in the browser and does not visit extracted destinations. Page buttons navigate within the PDF preview.
Keep the values and their context
Extract a focused list, check the source pages, and download the format that suits your next step.


